Current Projects
Each project has a corresponding configuration YAML file that defines its settings. These are used by various tools such as aidata to load data, download data, and argo-workflows to run processing pipelines. Use the links below directly in the tools or download the files to your local machine if you prefer. Contact the project lead for more information before using the data.
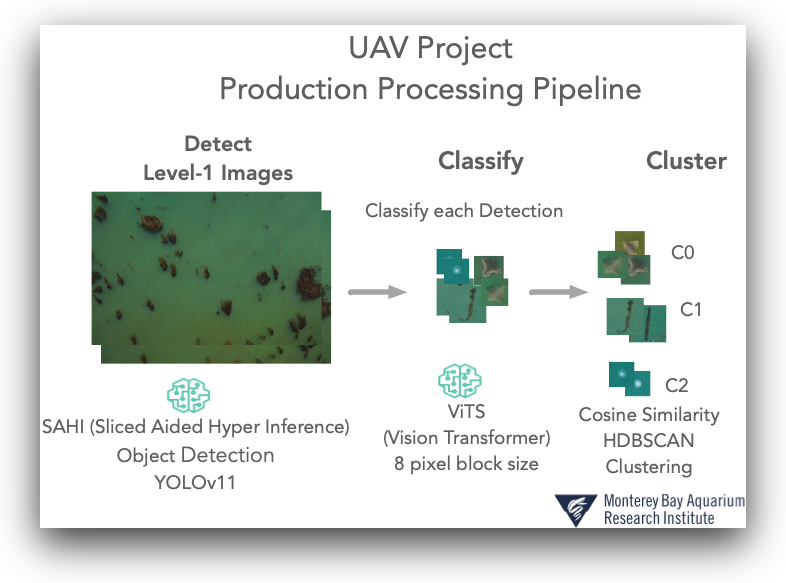
UAV Production Pipeline
This is the current production pipeline for the UAV project. It is used to process
high-resolution images collected by UAVs. Data from this is provided externally to drone.mbari.org.
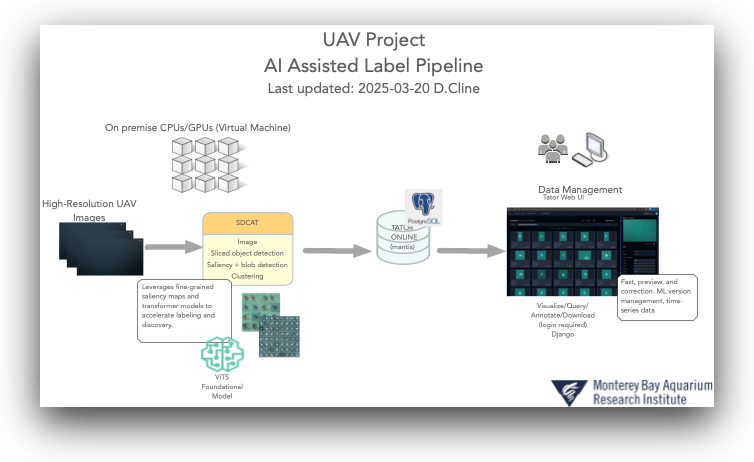
UAV Labeling Pipeline
This was the processing pipeline used to label the UAV images.
Output from this pipeline was used to train the two UAV models: for
one for detecting targets in the high-resolution UAV images,
and another for classifying them.
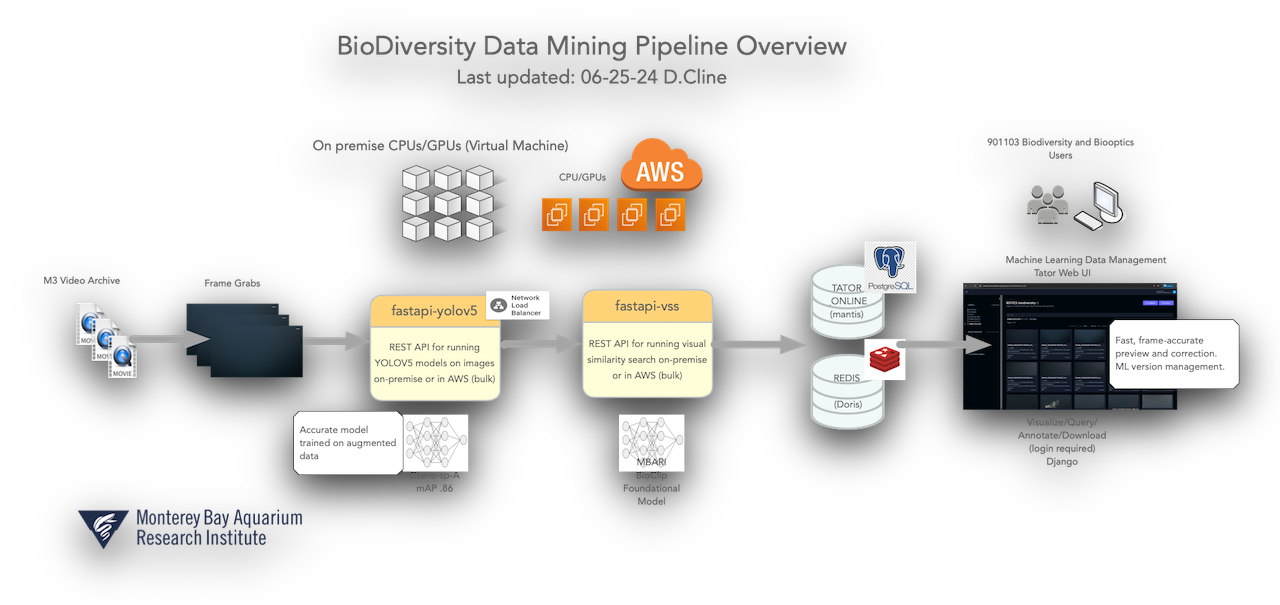
Data Mining Pipeline
This was used to mine data from the MBARI video archive.
- 📄 Project configuration YAML- images and some video
- 📄 Project configuration YAM Bulk i2MAP data - images
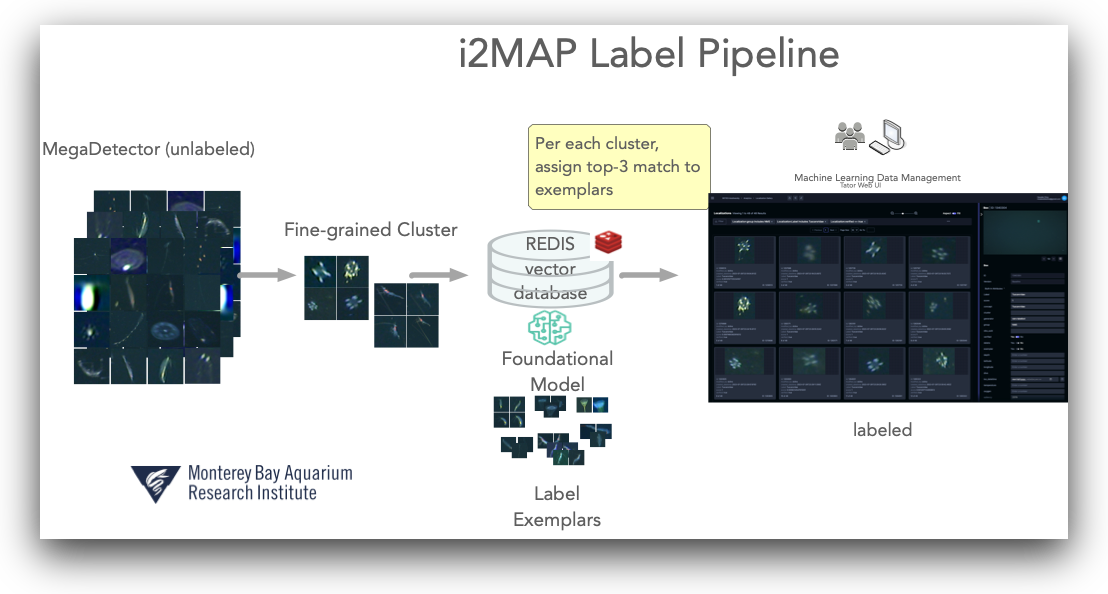
I2MAP Labeling Pipeline
This was used for initial I2MAP labeling. Images were extracted from ProRes videos
and then run through an accurate single-class "Megadetector" to find potential
targets, then assigned to the closest match by exemplar.
i2MAP Video
This is short example of the I2MAP video processed by a model trained on pseudo-labeled I2MAP data.
The RF-DETR model was used to detect and classify the targets in the video.
Simple bytetrack for tracking.
See the modelhub to try the RF-DETR model yourself.
- 📄 Project - 902111-ISIIS config YAML
- 📄 Project - 902111-ISIIS-Deployments YAML
- 📄 Project - 902111-Microscopy YAML
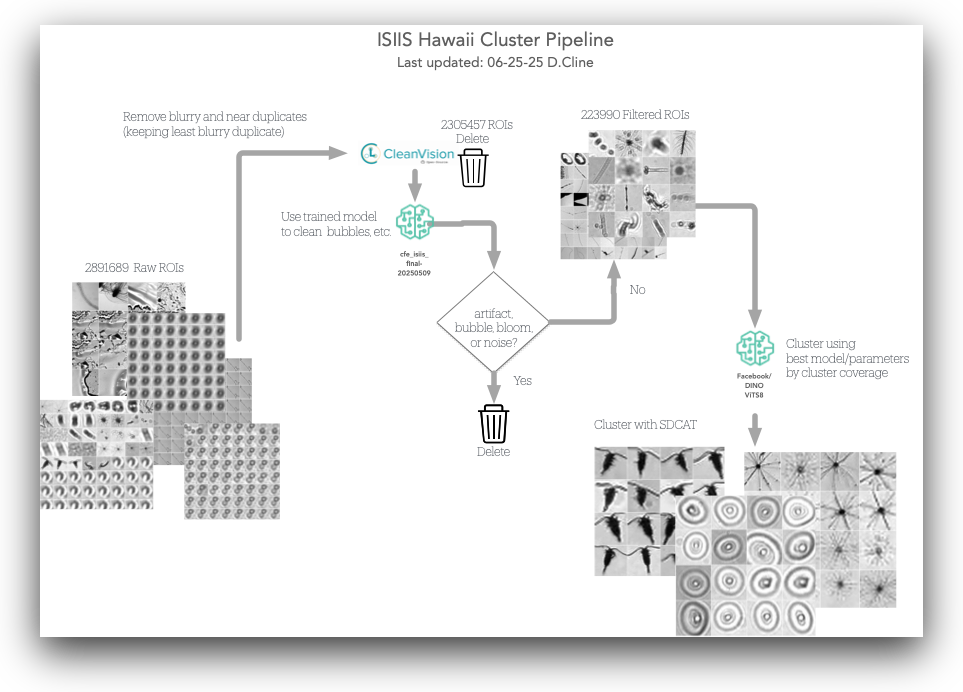
Hawaii ISIIS Clustering Pipeline
This was used to discover data from videos collected in Hawaii from the ISIIS camera.
This is the stage after images were extracted from the videos then ran through a detector
to find potential regions of interest (ROIs).
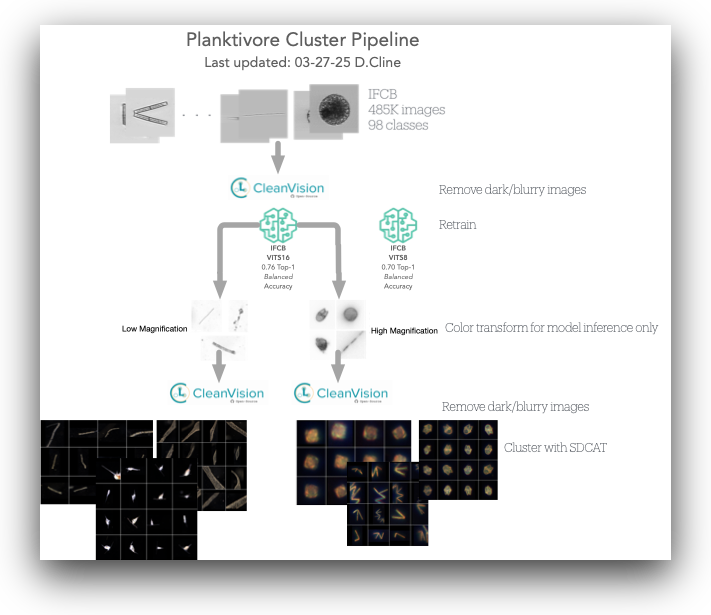
High Magnification Clustering Pipeline
This was used to seed data for the Planktivore model to classify particles.
Here, a classification model closer to the domain was trained using the publically
available IFCB dataset then used to cluster the particles.
- 📄 VARS training images config_vars.yml. See embargo policy before use
🗓️ Updated: 2026-03-24